🌍 Europe Only: Hardware sales & delivery exclusively within Europe
AI Factory
- Home
- AI Factory
// AI revolution
Purpose built datacenters for AI training
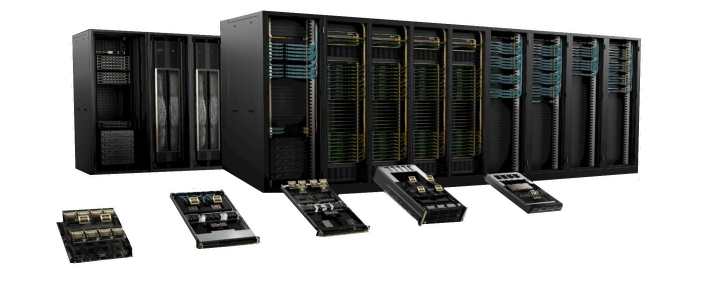
NVIDIA and the world’s top computer manufacturers unveiled an array of NVIDIA Blackwell architecture-powered systems featuring Grace CPUs, NVIDIA networking and infrastructure for enterprises to build AI factories and data centers to drive the next wave of generative AI breakthroughs. With datacenter being the new unit of measurement for generative AI training, AI factory systems are the perfect solution.
// Key components
NVIDIA AI Factory portfolio
Training and delivering AI models at-scale requires equaly capable infrastructure which is also scalable to customers needs. NVIDIA has a complete product portfolio which can build an AI factory under single ecosystem, keeping the controls and management simple, intuitive and accesible from anywhere.
GB200
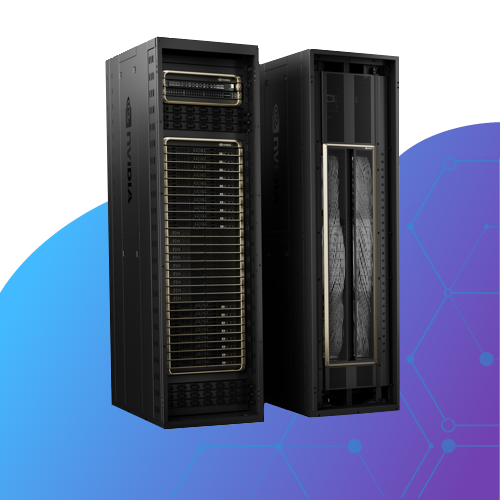
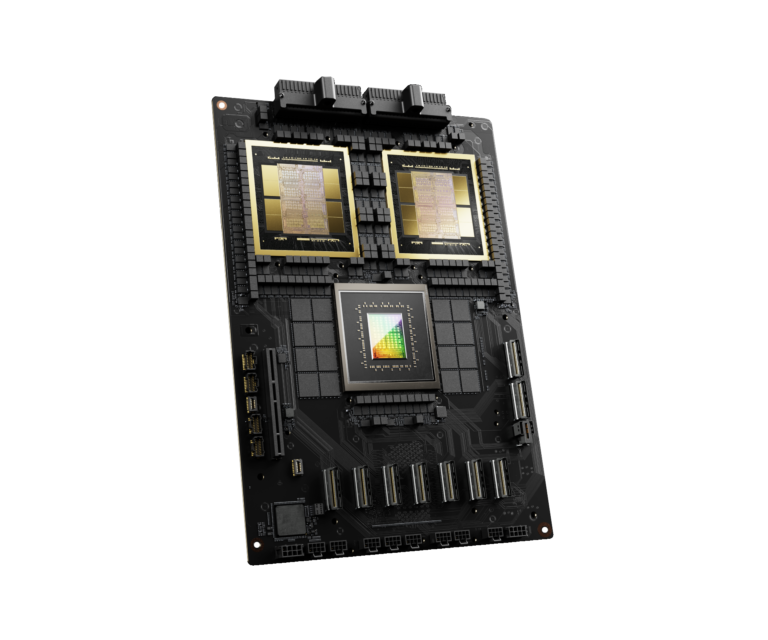
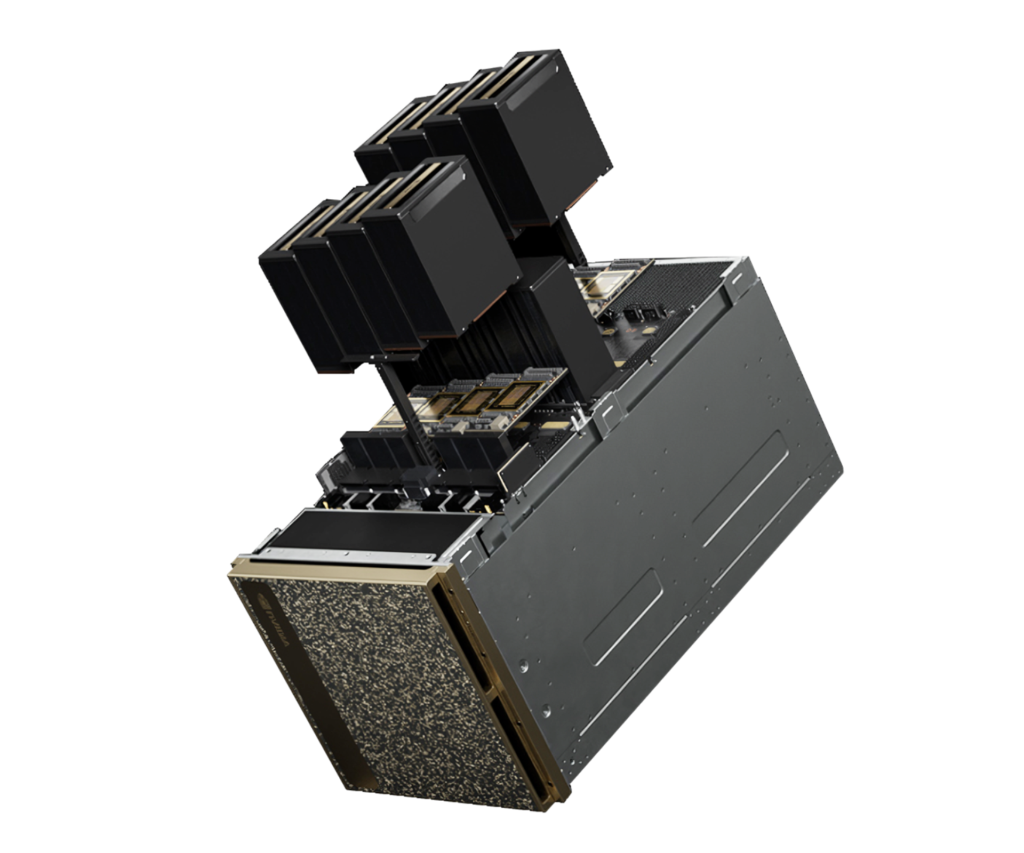
The NVIDIA DGX GB200 NVL72 is a datacenter scale solution for mass AI training and production.
CONFIGURE
GB200
NVIDIA GB200 NVL72
B200
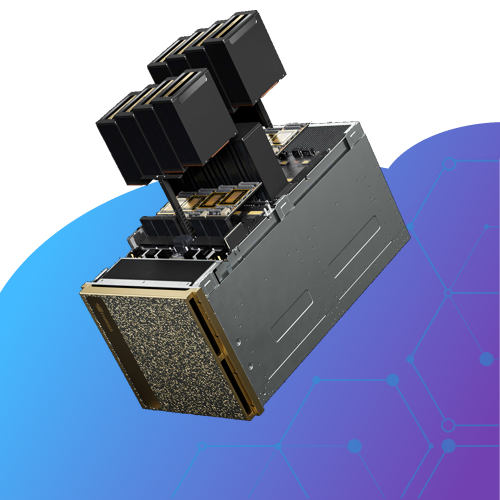
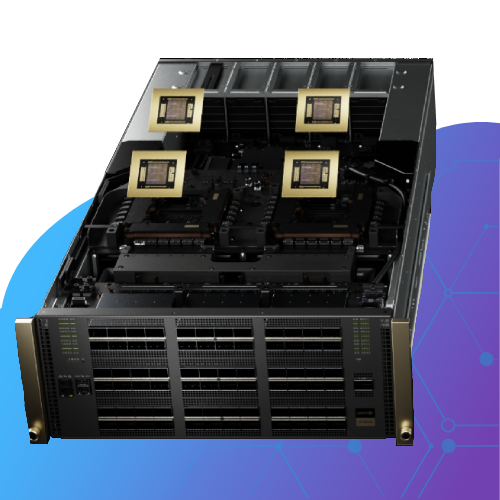
An extremely powerful professional AI and HPC solution built on Blackwell Tensor core GPUs - NVIDIA B200.
CONFIGURE
B200
NVIDIA DGX B200
X800
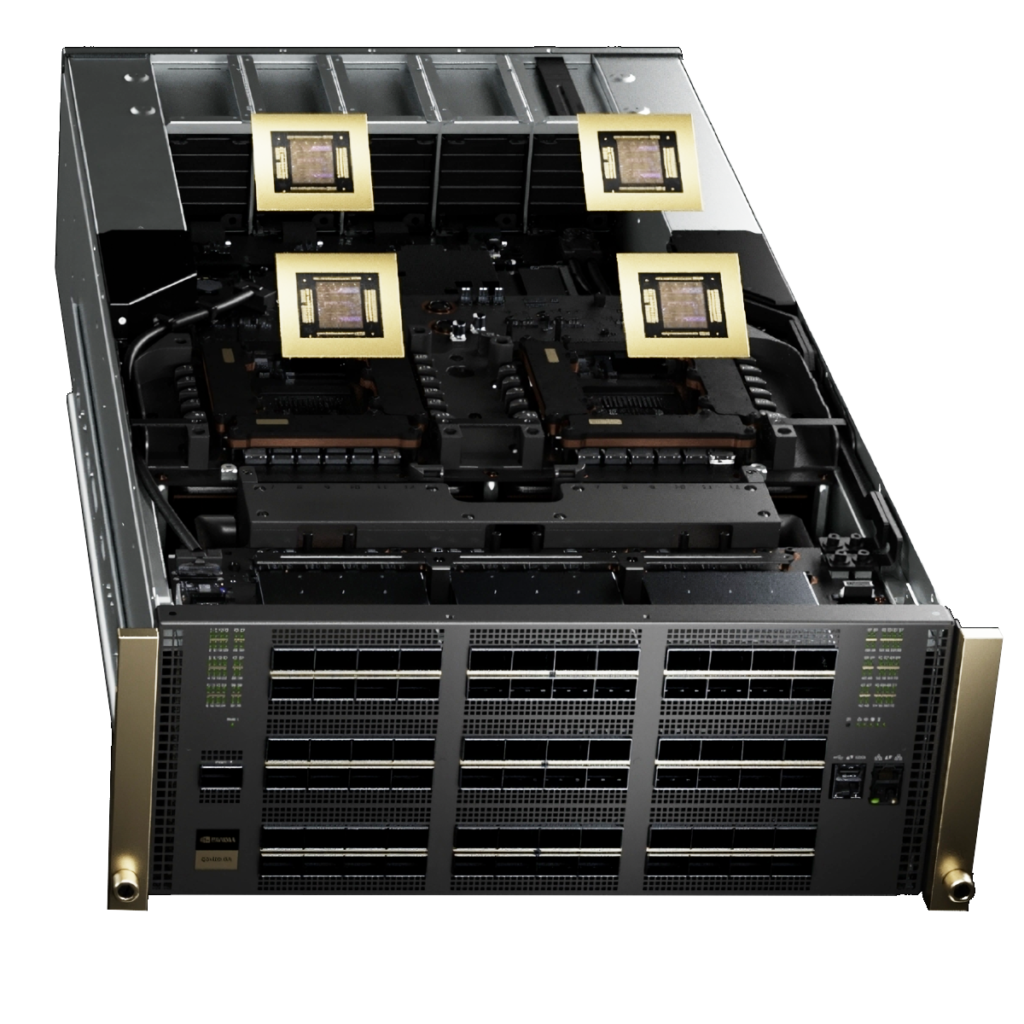
The NVIDIA Quantum-X800 is enabling super fast infiniband connections between all platforms.
CONFIGURE
X800
NVIDIA Quantum
Jensen Huang
NVIDIA CEO
"The next industrial revolution has begun. Companies and countries are partnering with NVIDIA to shift the trillion-dollar traditional data centers to accelerated computing and build a new type of data center — AI factories — to produce a new commodity: artificial intelligence"
// Why NVIDIA
Key benefits of NVIDIA powered AI system
Simplified solution
Simplify and scale AI deployments and operations with workflow automation.
Tailored to fit
Don't build a system that everyone tries to sell you - build one that you need.
Secure environment
Deploy your solutions into secure on-premises environment without endangering your data.
// Revolutionary Architecture
Accelerating AI with NVIDIA Blackwell
With the AI model size exponentionally growing, the need for adequate hardware in this sector is larger than ever and solid and scalable infrastructure, high power efficiency and data conidentiality are a fundamental qualities to keep the project on track.
As AI became a consumer-level commodity in today’s world, companies have to face various obstacles to satisfy this new, growing demand.
NVIDIA Blackwell architecture brings not only revolutionary performance and efficiency increase, but also a whole new concept of Datacenter purpose – an AI factory. A purpose-built datacenter scale compute clusters optimised for model training, inference, data processing and any other necessities acompanied with AI application development.
// Key benefits
Grace Blackwell superchip
B
Transistor count
PFLOPS
FP8 performance
GB
GPU memory
// Technology
AI Factory networking
NVIDIA RA (reference architecture) recommends a leaf-spine architecture with 400G InfiniBand for high-speed, low-latency connections between GPUs and storage, ensuring optimal performance for AI workloads. The architecture offers dedicated Ethernet switches for in-band and out-of-band management, maintaining a non-blocking network structure. Supermicro’s adaptation of this system scales from 32-node clusters to thousands of nodes, allowing telecom companies to build large-scale AI infrastructures efficiently. The robust network fabric supports NVIDIA GPUDirect RDMA, enhancing data transfer speeds and overall system efficiency, making it ideal for training and deploying large language models (LLMs).
// Technology
AI Factory compute
The compute section leverages NVIDIA DGX and HGX 8-GPU systems, featuring high-speed PCIe 5.0 slots and NVIDIA Quantum-2 400Gb/s InfiniBand networking. Each 8-GPU server offers substantial memory bandwidth via NVLink and up to 36TB of HBM3e memory, in case of H200 GPUs. This architecture supports extensive LLM training and AI model inference. The modular design allows for seamless scaling, connecting 32-node units into supercomputer-scale clusters with thousands of GPUs. The SuperCluster’s compute infrastructure is validated through rigorous testing, ensuring efficient, high-performance AI training and deployment in both air-cooled and liquid-cooled variants. Most of the reference architectures are built on H100/200 and GB200 accelerators.
// Technology
AI Factory storage
AI Factories require to process large ammount of training data, which has to be accessed with the lowest latency possible. NVIDIA RA offers various solutions from different vendors, each of them offering innovative solution to this problem. Such system includes GPU-direct working storage for immediate processing needs and tiered storage solutions for data ingestion, preprocessing, and archival. This architecture maximizes performance by ensuring efficient data flow between storage and compute resources. The system supports NVIDIA GPUDirect RDMA, which allows direct data transfers to GPU memory, enhancing speed and reducing latency. This comprehensive storage solution is essential for training and deploying generative AI models, enabling telecom companies to manage vast amounts of data effectively.